Xentient is Nandromeda’s architect: the brain that plans, manages and supervises the tasks you give to AI, so each one is done correctly with the best balance of performance and cost. Its aim is simple: finish every task successfully, as economically as possible.
Early access for teams that use AI at work.
Tell Xentient what “done” meansIllustrative example, not benchmark data.
Plan
Run
Verify
Learn
Cost per successful task$0.000
Built to work across the models you already use, and the ones that come next.
You wouldn’t send a lorry to deliver a letter. So why use a frontier model for every task?
AI doesn’t need one model for everything. It needs the right intelligence for the job—and a way to know when the job is actually done.
A lorry for a letter
An overpowered model
Wasted inference
Successful-task economics
Xentient
The number that matters
Cost per successful task.
A cheap AI that gets it wrong isn’t cheap. Every retry, every check and every hour spent fixing a bad answer is part of the bill. So we measure what a successfully completed task costs, all in.
#
Cost per successful task$0.000
Hover or tap a task to follow its path.
Illustrative example, not benchmark data.
Passed first timeRevised onceSort an incoming emailPull the fields from an invoiceSummarise a 40-page contractFix a failing test
Everything you spend
attempts, retries, checks, fixes
÷
Tasks that passed
checked and accepted
=
Cost per successful task
the number we work to lower
How it works
The core Xentient loop.
Plan, run, verify, learn: the core of Xentient’s six-stage system. We track one number: what it costs to get a task done right, not how many tokens you use.
01
Plan
Xentient, the architect, reads the task, works out what a good result looks like and plans the most efficient route to it, with quality first.
02
Run
The system does the work, using only what the task actually requires.
03
Verify
The result is verified against the task’s requirements. If it doesn’t pass, the system revises the approach and tries again.
04
Learn
Xentient remembers what worked and what didn’t, so similar work can start smarter next time.
Try a task
Pick a task. See how Xentient handles it.
An illustration of the path, not a live run: what happens between the task and the answer.
Plan
Xentient reads the task and defines what “done right” means.
Run · Verify
Learn
It records what worked, so the next similar task starts smarter.
Adapt
When a check fails, Xentient adapts and tries again.
Xentient doesn’t throw maximum effort at every task, and it doesn’t take a first answer on trust. When verification fails, it moves to a more suitable approach and tries again.
Passed first time
The first attempt got it right, so you paid only for what the task needed.
Revised once
Verification failed once, so Xentient moved to a more suitable approach and passed it.
Never passed silently
If nothing passes the check, the task is flagged, not returned as if it were done.
What we owe you
What we owe you, and what we’re about.
Plain commitments, in place of numbers we haven’t earned yet.
1
the number we work to lower
Work that’s done right
Every result is checked against what you asked for before it reaches you. If it fails, we fix it, not you.
Honest numbers
We publish a result only when we can show the method and the raw data. Until then, we say so.
A bill you can trust
We earn when you save. Pricing is tied to the savings we can verify, not to how much AI you burn.
Your data stays yours
We aim to keep nothing we don’t need, and we’ll publish our data policy before launch.
2026
founded in Istanbul, in September, to make AI work cost less to get right.
0
results published so far. The benchmark is in progress, and we’ll publish the method and the raw numbers.
Why Nandromeda
We don't optimize tokens. We optimize successful AI work.
Nandromeda · Istanbul
Products
The products, and the proof.
For business
Put an architect in charge of your AI.
Already running AI at work? Xentient connects to the models and tools you already use, then plans, supervises and verifies the work, so your team pays for tasks that succeed, not for work that gets wasted.
Xentient API
Send a task and what “done” means. Get back a verified result, plus the cost per successful task.
Partnerships
Building a product, cloud or platform? Build Xentient into it. Integrate, co-develop or resell with us.
Pilots
Start with one workflow. Measure cost per successful task against your current setup.
API access is by pilot for now. Nothing here is a published result.
ClaudeGPTGeminiLlama
XENTIENT
Your dataYour apps
Pricing
Priced by results, not by hype.
We’re pre-launch, so there’s no price list yet. This is the shape it will take.
01
Xentient for teams
A platform fee plus a share of the savings we verify, so we earn when you save.
02
ButterflyX
Start free. Upgrade when you need more.
03
Early access
Join the waitlist. Pricing is announced before launch.
From our founder
A note from our founder
I started Nandromeda because AI is already good enough to do real work, yet far too much of that work is wasted. The wrong model gets picked, nobody checks the answer, and you pay for every retry.
Xentient is our answer: an architect that plans each task, supervises it, verifies the result and learns from what happened. We’re building it in Istanbul, and we hold ourselves to one number: what it costs to get a task done right.
We’re opening to our first pilot teams now. If this is a problem you have, I’d love to hear from you.
Eniola Y. Oriyomi
Founder & CEO, Nandromeda
Be among the first to try it.
We’re opening to our first pilot teams. Tell us where to reach you and we’ll show you what your AI tasks could cost.
We'll reply personally — no auto-generated sales sequence.
Questions
What people ask first.
Something else on your mind? Write to us and we’ll respond soon.
What is Nandromeda?
Nandromeda is an artificial intelligence (AI) optimization company headquartered in Istanbul, Türkiye. Its flagship product is Xentient, an AI architecture engine for planning, executing, verifying, and optimizing AI work. Founded in September 2026, Nandromeda focuses on optimizing AI usage and the cost of successful AI work. The company is privately held and is currently raising $900,000 in pre-seed financing through a SAFE with a $7.5 million valuation cap.
How is Xentient different from a model router?
A router picks a model for each request. Xentient runs the whole operation: it defines what “done” means, plans the work, executes it, verifies the result and learns from the outcome. Choosing a model is just one of the decisions it can make.
Do I have to change the AI I use?
No. Xentient is designed to work with the AI models you already use, from the big providers to open models.
How do you know a task was done right?
We define what “done” means before the work starts, then verify the result against it with a test, a rule or a second opinion. Our metric is cost per successful task. We’ll publish the method and the raw results when the benchmark is ready.
Can I use it today?
Not yet. We’re pre-launch and building with our first pilot teams. Join the waitlist and we’ll let you know when there’s a place for you.
I’m technical. Where are the details?
The design, the metric we measure (cost per successful task) and the API sketch are on the . Investors will find the full picture on the .
First attemptRevised approachPassedFailedA quick classification, then a simple rule confirms the label is valid. Nothing more is used than the task needs.A light pass pulls out the fields, then a format check confirms every field is present and valid.The summary is drafted section by section. Verification spots a missing clause, so that part is redone with a more suitable approach, and this time it passes.A first fix is proposed. The test suite fails, so Xentient revises the approach and tries again, and the tests pass.TaskDone whenStakesBudgetisis any ofat mostTests passNothing missingFormat validAnswer matchesLowMediumHighAdd conditionClearSelect…Filter…No matches
AI work optimization engine
The most efficient way to get tasks done.
Pay for results, not tokens.
Xentient is Nandromeda’s AI work optimization engine. It runs the whole operation: it plans each task, executes it with the most suitable resources, verifies the result and learns from it, so every job gets done right at the lowest total cost.
Pick a task — see how it plays out, three ways:
Fix cost assumed:
Estimates for illustration: cost per successful task = model spend + fixing the failures, per task. Xentient figures are placeholders — not yet confirmed; tests are still being done.
What is Xentient?
Xentient is Nandromeda’s AI work optimization engine. It sits between your application and the AI systems you already use, with one job: get each task done right at the lowest total cost.
It isn’t a new AI model, and it isn’t just a router. Choosing a model is one lever among many. Xentient can trim unnecessary context, reuse cached work, break complex tasks into more efficient steps, or schedule non-urgent work when it makes economic sense. Then it checks the result.
A cheap answer that’s wrong isn’t cheap. That’s why Xentient optimizes for cost per successful task: total AI execution cost divided by the tasks that actually succeeded.
Cost per successful task = total execution cost ÷ successfully completed tasks
And it learns. Every outcome gives Xentient more evidence about what works, so the longer it runs on your work, the better it understands what “done right” means for you, and the more efficiently it can pursue it. The detailed scoring and evaluation logic is intentionally kept close for now.
How it works: the Xentient loop
Six stages. The core loop is Plan → Run → Verify → Learn. Understand defines what success means before the loop begins; Advise uses what Xentient learns to proactively improve future work. Work only leaves the loop when it passes.
01UNDERSTANDnow · in the benchmark
What does “done” look like? The stakes, the rules, the budget, the deadline.
02PLANnow · in the benchmark
The most efficient path likely to succeed, quality first: approach · resources · prompt · cache · split.
03RUNnow · in the benchmark
The system executes the plan, adapting resources to the work as it unfolds, with failover if a provider is slow or down.
04VERIFYnow · in the benchmark
The result is verified, not assumed: tests, schemas, exact answers, a judge. If it fails, the system adapts and tries again. Only successful results leave.
05LEARNwith pilots
Record what it cost and whether it worked — every prediction gets sharper.
06ADVISElater
Proactive suggestions to cut cost or failures, applied when you allow it.
◆ PERSONALwith pilots
Everything above is tuned per customer and stays private to them — the enterprise story.
Xentient at work, inside ButterflyX
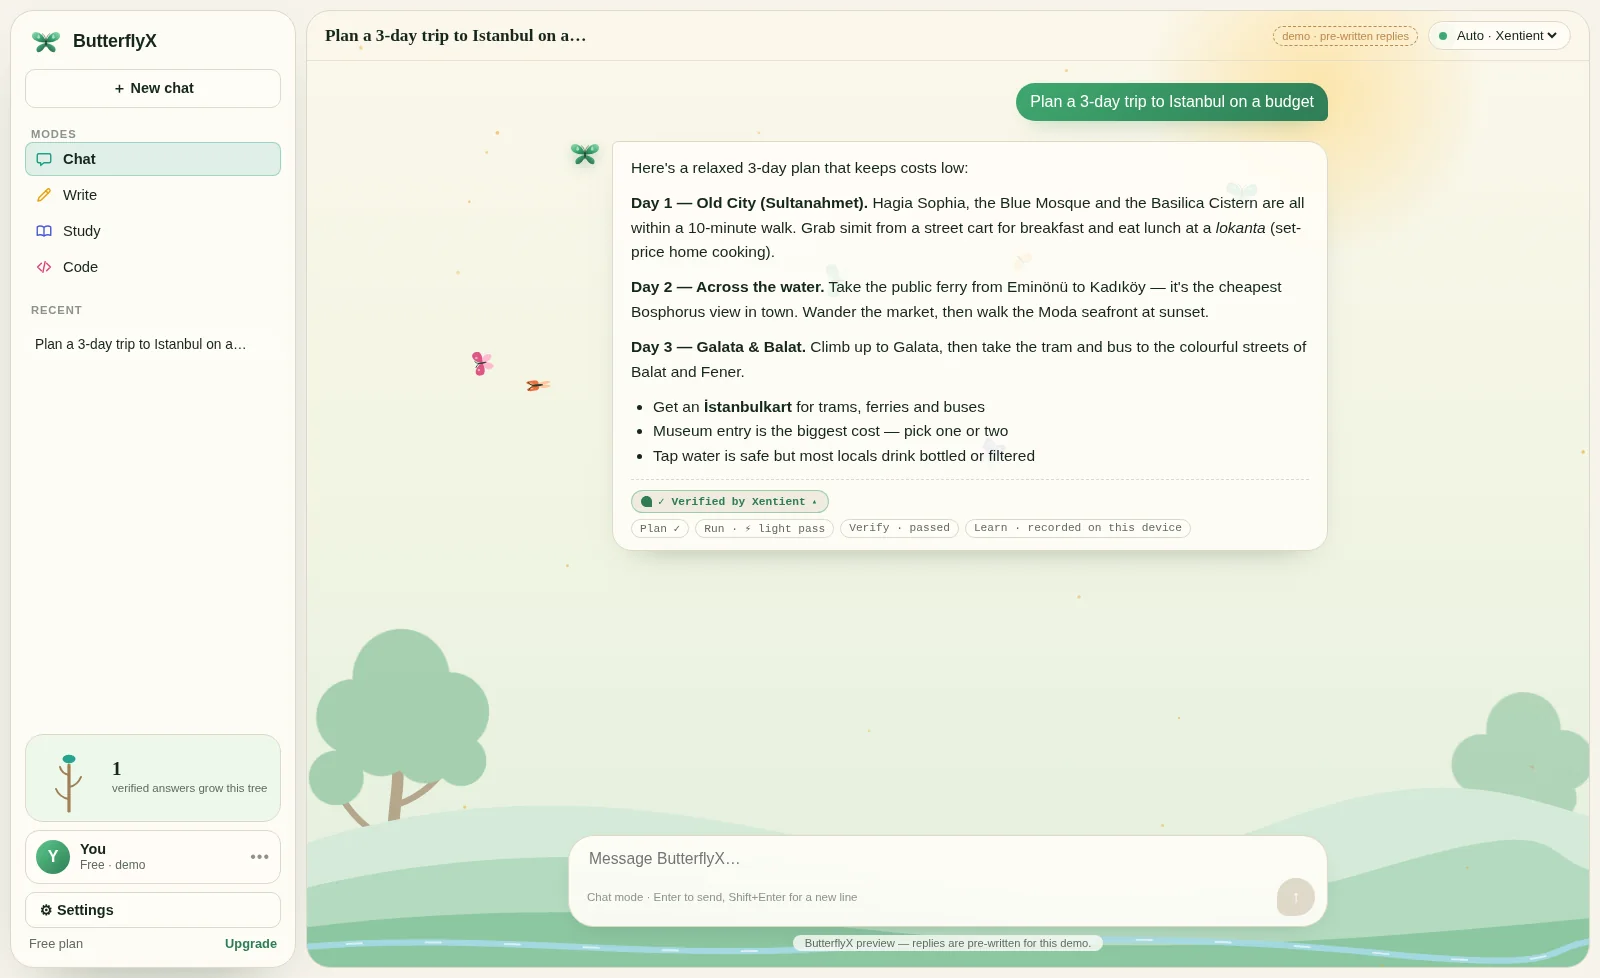
ButterflyX is our own AI app built on Xentient. Every message becomes a real Xentient task: planned, executed, verified and learned from. The chips under each reply make the process visible: how Xentient ran the task, how the result was checked, and whether it passed.
butterflyx
It checks its own work — by design
a candidate answer
→
the check
testsschemasexact answersjudge (only if needed)
→
✓ passes → delivered to you
✗ fails → adapt, checked again ↺
You get the savings when they're real, and the quality floor when they're not.
Honest status: plan, run and verify are what we’re building and benchmarking now. Learning and personalization come with pilots; the advisor comes later. No result is published yet.
Built to disappear into your stack
One integration point in front of your existing model calls. Xentient doesn't replace your models — it decides how each task should run across the ones you already use, and hands back only work that passed. Your quality bar stays yours.
Be the first to know
Xentient is being built alongside its first pilot teams. Leave your email and you'll hear first — when the benchmark lands, and when pilot slots open.
No spam — just a note when there's a pilot slot open.
Nano changes. Andromeda outcomes.
MISSION
Stop AI infrastructure from taxing every idea you ship
We exist to strip the waste out of running AI — every oversized model call, every failed attempt, every answer someone has to redo. Wasted AI spend is a tax on innovation. Our mission is to make sure it stops deciding what a team can afford to build.
VISION
We think about this the way engineers think about compilers: a layer beneath the code that optimizes automatically. We want to be that layer for intelligence — starting with Xentient, which lowers the cost of every successful AI task, and reaching over time toward the model and chip layers beneath it. Not a bigger model. A smarter layer underneath all of them.
ORIGIN
The name stacks three ideas: Nano, the smallest scale of change. NAND, the logic gate that's functionally complete on its own. And Andromeda, our nearest large galactic neighbor, roughly a trillion stars. The smallest, most unglamorous optimizations compound into differences too large to ignore.
ARTICLES · COMPANY THESIS
Notes on why we're building this
01
Nobody pays for tokens. They pay for work that's done.
Most teams pick one model per feature and stop thinking about it — a reasonable default, and a quietly expensive one. The invoice counts tokens, but the real cost includes every retry, every wrong answer and every human fix. The unit that matters is the successful task. Xentient exists to make it the number every AI decision is judged by.
02
Nano changes, Andromeda-sized outcomes
A NAND gate is almost nothing by itself — a handful of transistors — yet every digital system reduces to compositions of gates like it. One task done right for a little less saves a fraction of a cent. Multiply that across every task a growing product runs, for years, and the fraction becomes the difference between an AI bill being background noise or an existential cost.
Roadmap
Where we're headed
Directional, not a fixed schedule.
Now
Xentient core loop + public benchmark
Building plan → run → verify → learn, and measuring cost per successful task in the open.
Next
Learning, personalization & pilots
Outcome learning tuned per customer with the first design partners; pricing on verified savings. ButterflyX early access.
Later
Advisor, then dedicated small models
Proactive suggestions customers can accept; then small purpose-built models for the tasks they run most. Then Nandromeda's own models, in ButterflyX and through the API.
Moonshot
Independent enterprise LLM deployments
Private, efficiency-optimized deployments for companies wanting independence from big AI vendors.
Careers
Join the mission
No formal open roles yet — Nandromeda is early and small. But if cutting the waste out of running AI in production is a mission you want to help build, we want to hear from you.
Early collaborators & builders
Especially useful right now: ML/infra engineers, and anyone who's shipped LLM products in production and felt the cost pain firsthand.
Tell us what you'd want to work on — no formal application needed at this stage.
Press kit
For press & partners
CompanyNandromeda
Flagship productXentient
Based inIstanbul, Türkiye
StagePre-launch, pre-seed
One-linerNandromeda is an AI work optimization company. Its engine, Xentient, runs the whole operation, planning, running, checking and learning, and is measured by cost per successful task.
Consumer appButterflyX (in development)
Logo files and extended brand assets available on request — email hello@nandromeda.com.
FOR PROSPECTIVE INVESTORS
Who are we?
We're an Istanbul-based AI work optimization company, working in the layer between applications and the models they call. Xentient, our AI work optimization engine, gets each AI task done right at the lowest cost that still meets the quality bar, and gets better with every task.
We don't optimize tokens. We optimize successful AI work.
Full-screen, fourteen slides, about three minutes. The written version is below either way.
OR FLIP THROUGH IT HERE
Swipe, or tap a thumbnail. Tap the slide to open it full-screen.
THE PROBLEM
Tokens are getting cheaper. AI workloads are getting more expensive anyway
Teams default nearly all traffic to their single most capable model, regardless of what each task actually needs. That compounds silently until the AI infrastructure line item rivals headcount — and it's getting worse, not better, as agentic workflows call models more often and in longer chains. Gartner projects inference cost per agentic workflow could increase more than fivefold through 2028, even as per-token prices keep falling (Gartner, Aug 2026). AI gets cheaper per token and more expensive per business outcome at the same time — that paradox is the market.
THE SOLUTION
An AI work optimization engine, not another model — and not just a router
Xentient sits in front of existing AI calls and runs each task through a loop: understand what “done” means, plan the most efficient path likely to succeed, run it, verify the result, and revise the approach only when it fails. Every outcome is recorded, so it learns — and, per customer, personalizes. One integration point, no retraining. The metric isn't tokens saved — it's cost per successful task: everything spent, retries included, divided by the tasks that actually succeeded.
One company, one engine. Enterprises and developers use Xentient through our API, priced against verified savings. ButterflyX is our own app built on Xentient: a live showcase anyone can try, and a test bed that feeds the engine real outcomes. It will be free to start with optional subscriptions, but its job is to prove Xentient, not to be a second business.
Routing is real, and it's getting crowded — which validates the problem. OpenRouter and LiteLLM give excellent access to many models; Portkey is an enterprise gateway with routing, observability and governance (Portkey); Cursor and Factory run finely tuned routers inside their own coding products — Factory reports 63% lower cost at 99% of Claude Opus's pass rate (Factory, Sept 2026); and RouteLLM is open source (lm-sys). Each optimizes one layer of the stack, or one product. Nandromeda's thesis is different: make cost per successful task the primary objective — for any application, across providers — and prove it on the customer's own traffic. What compounds from that:
Outcome-based evaluation
Knowing whether a cheaper answer was actually good enough is the hard part. Deterministic checks where possible (tests, schemas, exact answers), model-based judging only where needed, and escalation whenever confidence is low.
Verified savings, not estimates
Every saving is measured against a baseline agreed with the customer, on their own traffic — and that same number is what pricing is based on.
Cross-workload learning
Support, extraction, RAG, agents: what we learn about which models succeed at which kinds of work compounds across customers — shared as general patterns, never as customer data.
Enterprise policy layer
Data residency, approved providers, and stakes-based rules (e.g. legal tasks always escalate) are part of every plan, not an afterthought.
BUSINESS MODEL — directional, not finalized
Priced against the value we create, not just usage
The plan is a platform fee sized to the customer, plus — for larger deployments — a share of verified savings: measured against a baseline of what the customer was spending before Xentient, so the pitch is arithmetic, not a promise. If we save a customer real money, that's provable and the pricing conversation follows from the number, not the other way around. Nothing here is a signed term sheet — it's the shape we're building toward.
TRACTION & STAGE
Pre-launch, building toward pilots
Domain, brand and product direction are set. Heads-down on the core loop and a public benchmark, with pilots next. Raising a pre-seed round now (the ask is below) — and always glad to talk to investors thinking about this space early.
THE ASK
What we're looking for
$900K on a SAFE — $7.5M cap
Introductions to early pilot customers, and investors who think about deep-tech / AI-infra efficiency plays are all useful right now — capital included, but not the only thing we're after at this stage.
Pre-seed SAFE, sized to where we actually are — pre-product, pre-revenue. Not a priced round, and not financial or legal advice; terms subject to counsel.
Use of funds — 18 months
Engineering & product (2 hires + founder)
55% · $495K
Design partners & founder-led sales
18% · $162K
Model compute & infrastructure
12% · $108K
Security, legal & company setup
10% · $90K
Buffer
5% · $45K
By month 18 — before the seed round
A public, reproducible benchmark: methodology, code, raw results and limitations
3–5 design partners in paid pilots, each with an agreed baseline
~$2M a year of customer inference spend running through Xentient
Lower cost per successful task on real traffic, verified against those baselines
A plan, not a promise — allocations will be refined with our investors.
We read every note personally. Want more than the deck? Ask and we'll share details directly.
NANDROMEDA — THE PITCH
Your AI gets cheaper per token.
It gets more expensive to run anyway.
That paradox is the market. We built the layer that closes it.
THE PROBLEM
Every AI company overpays. On purpose, by accident.
One model for every task. Cheap or critical, simple or hard — same expensive model, every time. Nobody decided this. It just happened.
5×
projected rise in inference cost per agentic workflow, through 2028 — Gartner, Aug 2026
THE INSIGHT
Cheap isn't cheap if it fails.
Model A gets it wrong 1 in 10 times. Someone has to catch the mistake and redo the task. That redo costs about $2.
Model A
$0.01 / request
90% success
$0.01 + (10% × $2 redo)
effective cost → $0.21
Model B
$0.10 / request
99% success
$0.10 + (1% × $2 redo)
effective cost → $0.12
Illustrative example assuming a $2 downstream remediation cost — not a live benchmark.
Naively: A looked 10× cheaper. Counting failures: B actually wins. The real metric is cost per successful task — not cost per token.
THE SOLUTION
Xentient. The most efficient way to get tasks done.
01Understand
→
02Plan
→
03Run
→
04Verify
→
05Learn
→
06Advise
Our AI work optimization engine. Failed work is re-planned and escalated; only verified results leave. Every outcome makes the next plan cheaper — tuned to each customer.
Pay for results, not tokens.
BEYOND ROUTING
Picking a model is one lever. We pull all of them.
Model & provider choice
Context trimming & caching
Task splitting & timing
Verification & escalation
Outcome learning & personalization
Later: dedicated small models
Now: plan · run · verify · escalate, in a public benchmark. With pilots: learning & personalization. Later: the advisor, then dedicated models.
WHY NOW
The timing isn't luck.
$23.4B → $197.5B
AI inference-as-a-service, 2026 → 2035
$11.5B → $37B
enterprise GenAI spend, year over year
73%
of enterprises spend $50K+/yr on LLM APIs
5×
projected rise in inference cost per agentic workflow, through 2028
Sources: Precedence Research · Menlo Ventures via Hostinger · Kong Inc. via Calliber. Full citations on the Prospective Investors page.
COMPETITION
Others optimize a layer. We optimize the outcome.
OpenRouter · LiteLLMaccess to many models
Portkeyenterprise gateway & governance
Cursor · Factoryrouters inside their own products
RouteLLMopen-source routing research
Nandromedacost per successful task — any app, any provider, verified on your traffic
A crowded routing market validates the problem. Factory reports 63% lower cost at 99% of Claude Opus's pass rate — inside its own product. We're building that outcome for everyone else.
THE MOAT WE'RE BUILDING
Anyone can build a router. What compounds with every deployment is outcome data.
Outcome-based evaluation
Verified savings, not estimates
Cross-workload learning
Enterprise policy layer
Routing is the entry fee. Knowing what succeeds is the business.
Every verified outcome teaches Xentient which approach succeeds on which kind of task — so each new deployment starts cheaper and more accurate than the last.
BUSINESS MODEL— directional
We get paid when you save money.
Enterprises: a platform fee plus, at scale, a share of verified savings. ButterflyX, our showcase app, is free to start with optional subscriptions.
You save $100K. We participate in the verified savings.
STAGE
Pre-launch. Building toward first production pilots.
Domain, brand and product direction set. Core loop in build; public benchmark next. Zero revenue — because we haven't opened the door yet.
Pre-seed SAFE, sized to where we actually are — pre-product, pre-revenue. Not a priced round, and not financial or legal advice; terms subject to counsel.
MILESTONES
By month 18 — before the seed round
A public, reproducible benchmark: methodology, code, raw results and limitations
3–5 design partners in paid pilots, each with an agreed baseline
~$2M a year of customer inference spend running through Xentient
Lower cost per successful task on real traffic, verified against those baselines
A plan, not a promise — allocations will be refined with our investors.
THE LONG RUN
From the most efficient way to get a task done — to the efficiency layer beneath all intelligence.
TodayThe most efficient way to get each AI task done
NextA layer that knows your work
LaterDedicated small models
Long runThe efficiency layer beneath all intelligence
ButterflyX, our own app built on Xentient, shows it to everyone: everyday AI with Xentient inside — and, one day, our own models.
NANDROMEDA
We don't sell AI.
We make the AI you already bought cheaper to get right. Provably.
01 / 14
XentientClaudeGPTGeminiLlamaYour dataYour apps
Xentient sits between your AI and your work: it connects, plans, supervises and verifies.
For business
Put an architect in charge of your AI.
Xentient connects to the models and tools your teams already use, then plans, supervises and verifies every task, so you pay for work that’s done right, and can show it.
API access is by pilot for now. Nothing here is a published result.
The problem
AI spend is easy to see. Whether it worked is not.
1
One setup for everything
Most teams send every task to their most capable setup, whatever the task needs. The cost compounds quietly.
2
Nobody checks
Results go out without a check tied to what the task actually required.
3
No unit cost
You see tokens and invoices, not what a successfully completed task costs.
What you get
An architect, not another model.
Define “done”
Say what a good result looks like: a test, a schema, a rule set or a human review. Xentient works to that.
Plan and supervise
Each task is broken into steps, given only the resources it needs, and watched while it runs.
Verify before delivery
Every result is checked against its requirements. If it fails, the system revises the approach and tries again.
Cost per successful task
One number finance and engineering can both read: total cost ÷ tasks completed successfully.
Your models, your rules
Works with the models and tools you already use. Stakes and policies decide when a person must review.
Your data stays yours
Designed to run inside your environment, with what it learns kept private to you.
Full power
One month-end VAT return, start to finish.
An illustration of how Xentient would run a large, high-stakes job: 4,200 invoices turned into a checked draft return for an accountant to review.
TaskPrepare the monthly VAT return draft from 4,200 supplier invoices
Definition of done
Every invoice is classified
Totals reconcile to the ledger
Rates match the rules for each item
Exceptions are flagged, not guessed
A person signs off before filing
Stakes: highDeadline: 5 working daysData stays in your environment
1Read and extract invoice fieldsLightStandardDeep
2Classify each invoiceLightStandardDeep
3Match to ledger entriesLightStandardDeep
4Apply the rate rulesLightStandardDeep
5Resolve exceptionsLightStandardDeep
6Compute totals, draft the returnLightStandardDeep
7Cross-check with last quarterLightStandardDeep
8Write the accountant’s summaryLightStandardDeep
214 invoices don’t match the ledgerRevised with a deeper pass, checked again
Xentient turns the request into a checkable definition of done, with the stakes and the deadline.
The job is split into eight steps, each given the lightest setup likely to pass.
Steps execute in order, adapting resources as the work unfolds.
Every result is checked. One step fails, so the system revises its approach and tries again.
What worked, what didn’t and what it cost is recorded for next month.
Later, Xentient will suggest changes, such as cleaning up duplicate suppliers first.
Verified draft return, ready for a person to review.
Cost index, illustrative
With Xentient0
Always the deepest setup100
An illustration with made-up numbers to show the shape of the work. It is not a benchmark or tax advice; a qualified person signs off before anything is filed.
Work with us
Three ways in.
Xentient API
Send a task and what “done” means. Get back a verified result, plus the cost per successful task.
Partnerships
Building a product, cloud or platform? Build Xentient into it. Integrate, co-develop or resell with us.
Pilots
Start with one workflow. Measure cost per successful task against your current setup.
How a pilot works
1Pick one workflow
2Define what “done” means
3Run beside your current setup
4Compare cost per successful task
Pilot slots are limited while we’re pre-seed.
Bring us one workflow.
Tell us what your teams run on AI today. We’ll tell you how Xentient can help.
// for developers
Pay for tasks that pass — not tokens that don't.
Xentient is an AI work optimization engine in front of your model calls. You define what “done” means — a test suite, a schema, an exact answer, a rubric — and it finds the most efficient path that meets it, verifies the result, and revises the approach only when it has to. Below is the current design, not a live API yet.
Outcome simulator
Describe a task, say what “done” means and how much is at stake — then watch the loop plan, run, verify and learn.
Illustrative simulation, not connected to a live model or real cost data.
The same engine, in ButterflyX's code mode
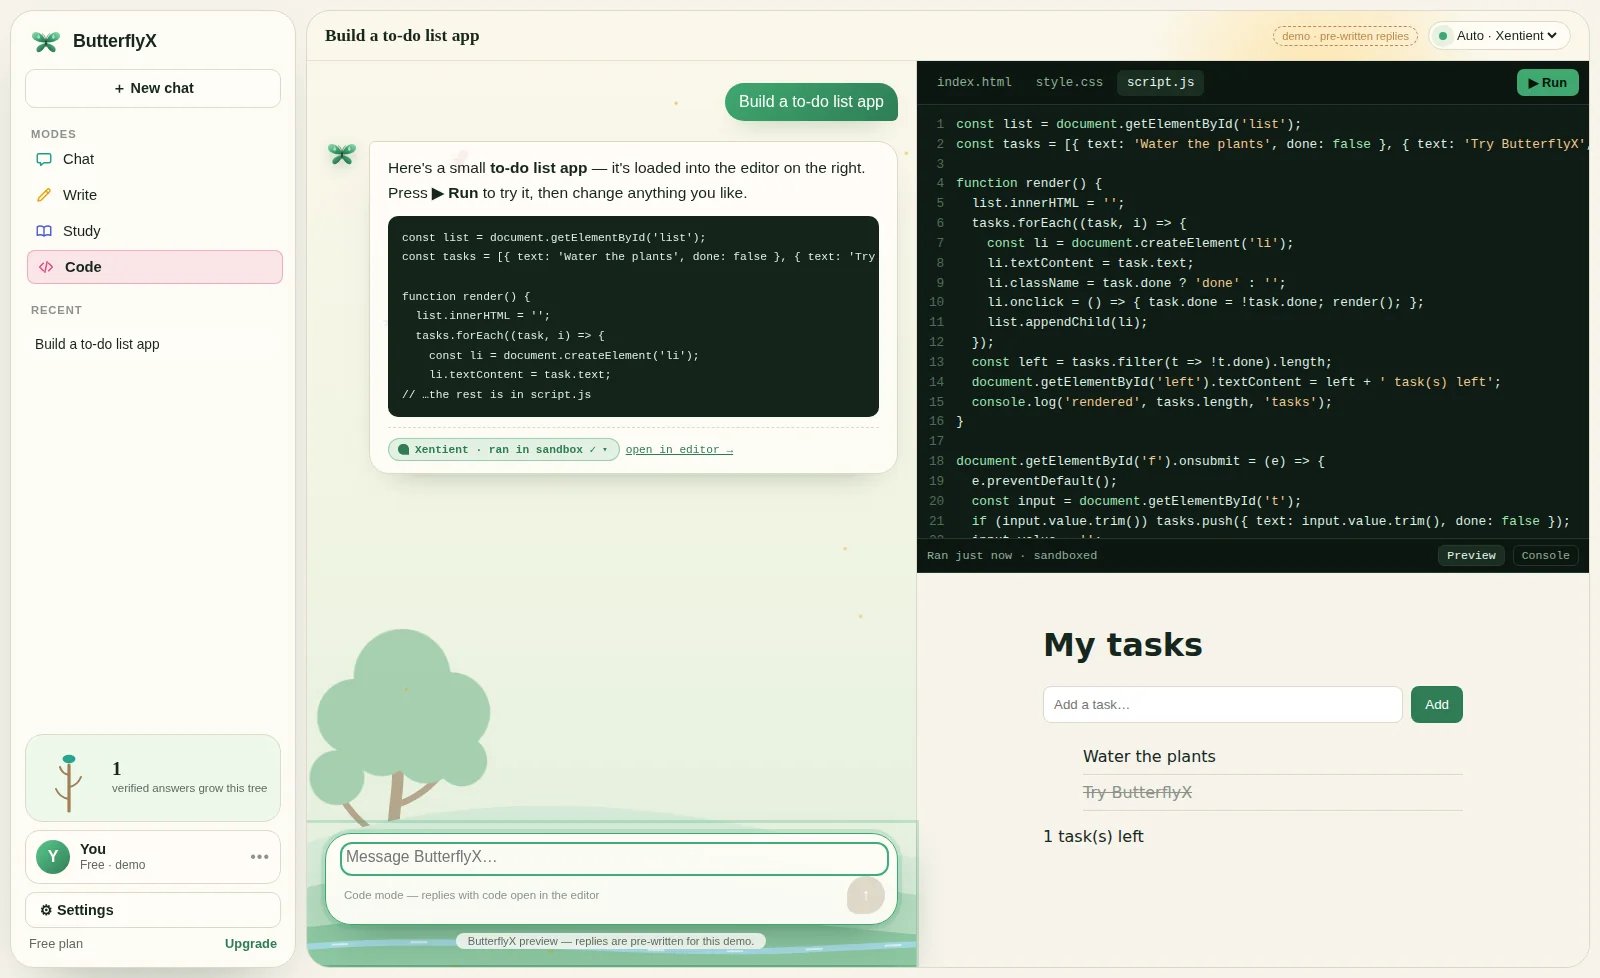
Our consumer app is being built on the same engine you'll use: code requests are planned, run in a sandbox and checked before they reach the editor. Open the demo in code mode →
butterflyx · code
Code mode: ask for an app, then edit and run it in the built-in IDE.
Technical pillars
Every pillar points at one number: a successful task at the best price possible. Nothing here optimizes a proxy.
Definition of done
You say what success looks like — tests, schemas, exact answers or a rubric. Every decision is scored against it.
Verify before delivery
Deterministic checks first, model-based judging only where needed. Failing work never leaves — it’s re-planned and retried.
Levers beyond routing
Model and provider choice, context trimming, caching, task splitting and timing — whichever combination makes this task pass for the least.
Outcome learning
Every attempt is recorded with its cost and result, so the next plan for similar work starts smarter. Per customer, private by default.
Guardrails & policy
PII, high-liability and ambiguous tasks escalate automatically; approved providers and data-residency rules are part of every plan.
Failover
If a provider is rate-limited or down, the task fails over to another path that meets the same bar.
Integration shape
This is the interface we're designing toward — not a published package yet.
Beforetoday
# one model for everything — you pay for every attempt, right or wrongfrom anthropic import Anthropic
client = Anthropic()
response = client.messages.create(model="claude-opus-4", messages=[...])
Afterplanned
# say what "done" means — Xentient finds the most efficient path that meets itfrom xentient import Xentient
xt = Xentient(api_key="xt_...")
result = xt.run(
task="Extract the invoice fields",
input=invoice_pdf,
done=xt.schema(Invoice), # or xt.tests("pytest -q"), xt.exact(...), xt.judge(rubric)
stakes="low",
)
result.output # only returned if it passed
result.cost # everything spent, retries included
result.trace # the path it took: plan → run → verify → …
Honest status: this is the target interface — not installable yet. Join the list on the Xentient page to hear first when it is.
Reliability & security posture
Data retention
Intent is zero unnecessary retention of prompt content. A formal policy lands before general availability.
Compliance
We do not hold SOC 2, HIPAA, or similar certifications yet — pre-launch. We won't claim them until real.
Latency overhead
No published benchmark yet. We'll share measured numbers once we have pilot traffic.
Multi-provider fallback
Designed in from the start — a plan can always fall back to another provider that meets the same bar.
BUILT ON XENTIENT · COMING SOON
ButterflyX
Everyday AI for everyone, with less wasted work.
Xentient inside
ButterflyX is our own everyday AI app, built on Xentient to show what it does: chat, write, study and code in one place. Xentient plans, runs and verifies every answer, so you get the same capable AI with less wasted work and a lower cost of getting things done. Start free; upgrade when you need more.
The demo runs in your browser: replies are pre-written, the code editor is real.
butterflyx
ButterflyX chat: every reply shows how Xentient ran the task, how it was checked, and whether it passed.
One app, every kind of task
Chat & write
Emails, plans, summaries and ideas — in plain words, in your language.
Study
Step-by-step explanations that check their own working before you see them.
Code, with a built-in IDE
Ask for code, then edit and run it right beside the chat — no setup.
Efficiency, in Settings
Settings shows how much compute your answers used compared with sending everything to a large model, with the method one tap away.
Code mode, with an IDE built in
Not just a chat box. When you ask for code, ButterflyX opens it in a mini IDE right beside the conversation — edit it, run it, see the console, and ask for fixes without leaving the app.
butterflyx · code
Code mode: ask for an app, then edit and run it in the built-in IDE.
Built for everyone
Students, parents, shop owners, writers, developers. The same capable AI, with less wasted work and a lower cost of getting things done.
Plan
Run
Verify
Learn
Verified by Xentient
Plan
Run
Verify
Recorded on this device
Different people. Different work. One underlying intelligence.
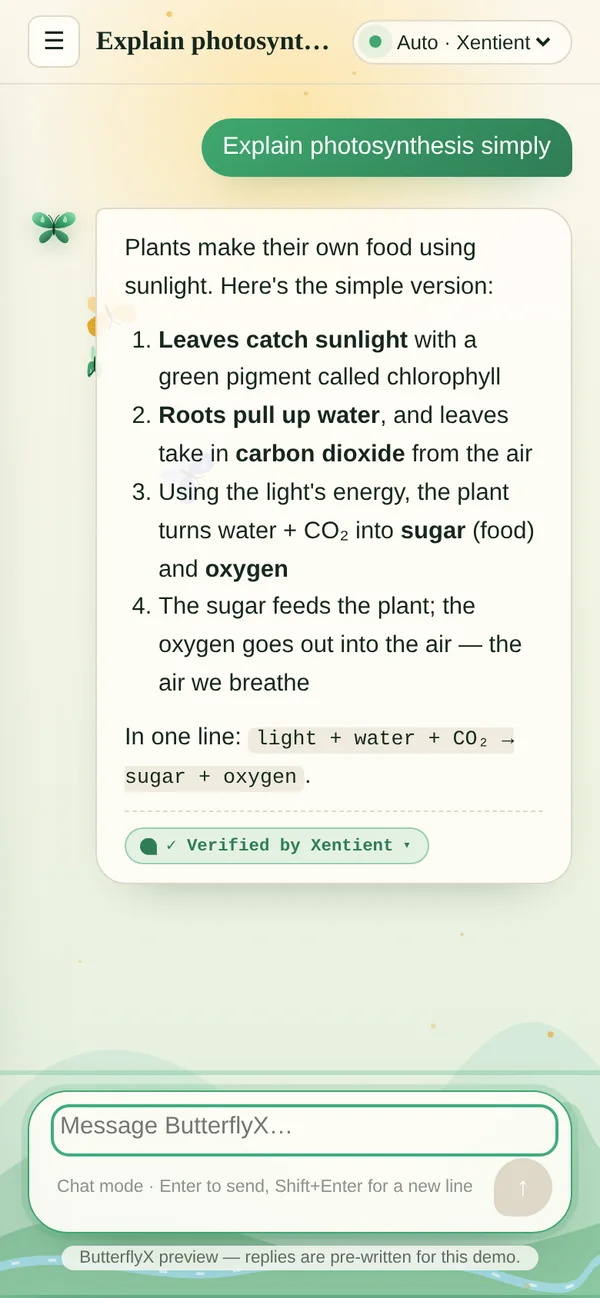
StudentExplain photosynthesis in simple steps.1. Leaves catch sunlight.
2. Roots bring up water; leaves take in carbon dioxide.
3. Light turns them into sugar, the plant’s food.
4. Oxygen is released into the air.Shop ownerReply politely to a customer whose order arrived late.Hi Sara, I’m sorry your order reached you late. I’ve refunded the delivery fee, and your next order will ship first. Thank you for your patience.WriterTighten this: “He was very tired and he really wanted to go home.”“Exhausted, he wanted to go home.”
Five words shorter, same meaning.DeveloperWhy is my total wrong? items.reduce((s, i) => s + i.price)reduce has no starting value, so the first item (an object) becomes the total. Pass 0:
items.reduce((s, i) => s + i.price, 0)ParentPlan five quick, cheap dinners for this week.Mon lentil soup · Tue veggie pasta · Wed egg fried rice · Thu chickpea curry · Fri homemade pizza.
One shopping list, about 30 minutes each.
Why it’s efficient
AI should work smarter, not just harder.
Only what the task needs
You don’t need the biggest AI for every question. ButterflyX uses what the task actually needs.
Less waiting around
Unnecessary work is avoided, repeated work can be reused, and simple tasks don’t have to take the long way around.
It checks itself
ButterflyX doesn’t just generate an answer and move on. Xentient checks whether the result actually meets the task.
It learns your patterns
The more you use it, the more Xentient can understand which approaches work for the kind of work you do.
Less wasted AI
Fewer unnecessary calls, retries and computations mean less wasted AI spend.
You don’t have to think about any of this
That’s the point. You ask. ButterflyX handles the work underneath.
Free to start. Plans when you need more.
Freemium with monthly subscriptions. Pricing will be announced at launch.
Today, ButterflyX runs on Xentient, optimizing how every task gets done across leading AI models. Tomorrow, it will also run Nandromeda’s own models, in ButterflyX, on other platforms, and for developers. Building a product? The same Xentient engine will be available to businesses through the Xentient API.
AI that gives back
A share of ButterflyX profits will support water-restoration projects. We’ll publish where it goes.
Be first in line
ButterflyX is in development. Join the waitlist and we'll let you know when early access opens.
No spam — one note when early access opens.
Honest status: ButterflyX is in development and not yet released. The demo runs in your browser with pre-written replies; efficiency figures in Settings are estimates with the method shown.
Last updated: September 28, 2026
Heads up: Nandromeda is a pre-launch startup. This is a plain-language starting draft, not final legal advice — it should be reviewed by a lawyer familiar with Turkish (KVKK) and, if we take on customers elsewhere, EU (GDPR) data law.
Privacy Policy
We collect an email address (and a name or company, if you add one) only when you submit a waitlist, demo, contact or deck-request form. Those submissions are stored on our own web host and forwarded to our inbox, and are used only to reply to you or contact you about early access — never sold or shared. When you request the deck, your name and email are passed to EmailJS (our email-delivery provider) solely to send you that email — see their privacy policy at emailjs.com. To understand how the site is used, we run Umami, a privacy-focused analytics service: it sets no cookies, doesn't store your IP address, and records only anonymous visit data — the country and city your connection comes from, device and browser type, the site that referred you, the pages and pitch-deck slides viewed, and actions such as downloading the deck. You can switch it off with the banner's “Reject non-essential” button, and it's automatically off if your browser sends Do Not Track or Global Privacy Control.
Ask us to delete your email at any time via hello@nandromeda.com. GDPR/KVKK rights apply where relevant.
Terms of Service
Figures shown on this site (cost savings, success rates, cost per successful task) are illustrative unless stated otherwise, and are not a guarantee of results. This site and any pre-release product are provided "as is" during early development. Governed by the laws of the Republic of Türkiye, pending formal incorporation and legal review.
Cookie Policy
We don't use cookies. We keep at most two small items in your browser's local storage: your cookie-banner choice and — only if you reject non-essential — a flag that switches analytics off. Neither is used for advertising or shared with anyone. Our analytics (Umami) is cookieless and stores nothing on your device.
Get in touch
Tell us what's up — we read every message ourselves.
Opens your email app with this pre-filled.
Get the deck
Quick intro so we know who's asking — then it's yours.
Your PDF will download right away.
We store one small preference in your browser and collect anonymous, cookie-free visit stats to improve the site. No ads, no cross-site tracking.